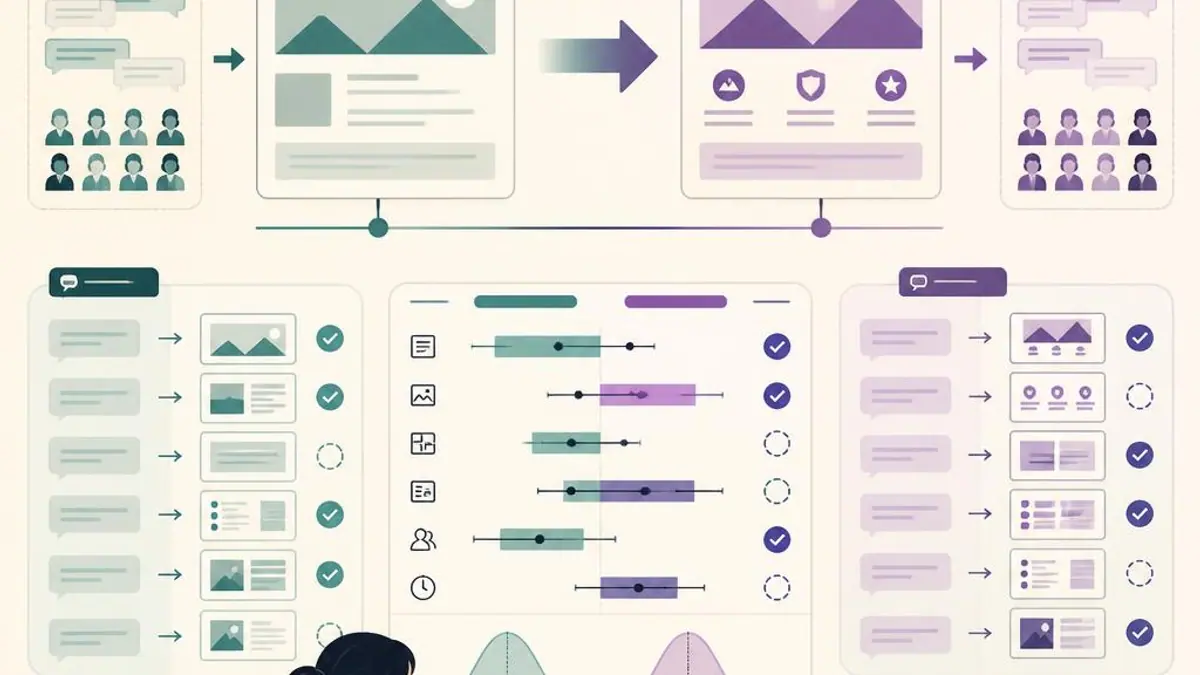
Compare AI visibility using an unchanged prompt cohort, documented settings and repeated dated observations. Annotate the content release, but avoid claiming that the release caused every later change.
Freeze the comparison before publishing
Select the prompts and engines in advance. Save the baseline output, intended URL and classification rules. Write down what the page change is intended to improve, such as answering an eligibility question more clearly.
Keep new prompts separate from the original cohort. Otherwise an apparent gain may simply reflect replacing difficult questions with easier branded ones.
Repeat with consistent settings
Record the same available location and language settings, dates and engines. Inspect answer availability before calculating a rate. Where the provider exposes no reproducible setting, state that limitation rather than claiming a controlled experiment.
An illustrative before-and-after log should include the actual source URLs, not only a score. A citation that moves from one owned page to another may require a different interpretation from a newly acquired citation.
Interpret change as observation, not automatic causation
Other pages, provider behavior, retrieval freshness and user context can change at the same time. A before-and-after comparison can guide a decision but does not isolate all causes. Repeat checks and review source-level evidence.
Choose the next action from the information gap that remains. Preserve the baseline and earlier drafts, even when a new version performs differently, so future reviews do not lose the original evidence.
Write the before-and-after question precisely
Define what you intend to compare: organic query performance for one page, a saved prompt sample, citations in a set of answers or another outcome. Set the page or cohort, market, engine and comparison periods before looking at the result. The outcome should be narrow enough to reproduce.
Record the start and end dates, exact prompts, filters and product versions. Identify material changes other than the page edit, such as a site migration, updated offer or engine interface change. A comparison without this context can make two different studies look like one.
Change the page for a stated user benefit
Write down the verified issue and the edit made to address it: corrected contact facts, clearer service limits, a missing process step or a stronger source explanation. Preserve the earlier text and the publication date. Avoid changing many unrelated sections at once if the team wants to understand what happened.
A change should be defensible even if external search signals do not move. Accurate, accessible information and working links are outcomes the site owner can verify. No keyword rewrite is guaranteed to cause an engine to select a page.
Repeat comparable checks and keep failures visible
Reuse the same query and prompt cohort, locale, language, date-handling and classification rules. Record failed or unavailable requests instead of comparing them to successful answers. If a question has materially changed or a feature no longer exists, mark that cohort as a new study.
For organic results, compare equivalent time windows while noting known seasonal patterns and data limitations. Do not treat a small movement in average position as a universal ranking for all users or locations. Keep clicks, impressions and AI answer observations separate.
Report the result and the uncertainty honestly
Summarize what was edited, what your chosen data source showed and which observations were missing. If the sample changed in a favorable direction, describe the sample and period instead of asserting that the change will hold for every query or user.
If nothing changed, do not immediately add text or repeatedly resubmit the same URL. Revisit whether the page answered a genuine need, whether access is correct and whether more observation is justified. Sometimes the right decision is to leave a working page unchanged.
Prepare a comparison worksheet before collecting the after sample
List the changed URL, change description, release time, baseline period, follow-up period, prompt cohort and source filters. State which measures are descriptive and what would count as missing data. Keep the worksheet with the saved evidence so another reviewer can reconstruct the comparison.
If a condition changes, annotate it rather than quietly forcing the new result into the old series. A new question version, additional market or different engine mode may be useful research, but it is not an identical repeat. Report it as a new or qualified cohort.
An illustrative ambiguous result
Imagine that a page update is followed by one additional citation in a small prompt sample while organic clicks remain sparse. The defensible finding is that the saved sample differed after the release under the recorded conditions. It is not proof that the update caused the citation or that customers are now more likely to buy.
Inspect the answer and source page to confirm what actually changed, and preserve any missing or failed observations. A promising pattern can justify continued monitoring. It should not be converted into an unsupported percentage of all users or a guarantee that the result will repeat.
Choose the next action using evidence strength
If a direct technical check still fails, fix it before extending the performance study. If the page is accurate and the sample remains too small, wait for more useful data. If customer questions reveal a clear missing explanation, plan a focused improvement with its own release annotation.
Keep no change as a legitimate decision. Rewriting a working article after every fluctuation creates editorial churn and destroys a stable comparison. Record why the team chose to act or wait and what future observation would alter that decision.
A before-and-after interpretation checklist
Use this checklist before turning a changed observation into a performance claim. The objective is to describe comparable evidence and choose the next action, not to force a success narrative from limited data.
- The baseline and follow-up use the same defined outcome, cohort, language, market and source filters where comparison requires them.
- The release annotation names the URL, actual change date, reader benefit and other known changes during the period.
- Unavailable requests, sparse organic data and changed collection conditions remain visible instead of being converted to zero.
- Counts and denominators can be reconstructed, and percentages are not presented as population-wide rates.
- Any claimed recommendation is supported by explicit wording, not merely a name mention or linked reference.
- Causal language has been removed unless independent evidence supports attribution beyond temporal sequence.
- The next action follows a verified issue or stated hypothesis, and waiting remains an acceptable choice when evidence is insufficient.
Apply this workflow in RankZoro
Start with measurement and reporting and review the relevant RankZoro capability. Use the output to organize evidence and editorial work, not as a guarantee of search inclusion. Compare plans before running paid or credit-based actions.
Continue with How Agencies Can Report AI Visibility Without Overclaiming Results or Search Console and AI Visibility: Two Different Evidence Sources. These are supporting explanations, not independent proof of measured outcomes.
Sources and methodology
- Google: AI features and your website — Eligibility, search fundamentals, and reporting limitations.
- Google: creating helpful, reliable content — People-first content and evidence of experience.
- Google: spam policies — Doorway pages and scaled content abuse are not an expansion strategy.
Prepared by the RankZoro editorial team. Examples are illustrative unless explicitly identified as observed data. No customer outcomes or search-volume estimates are claimed.