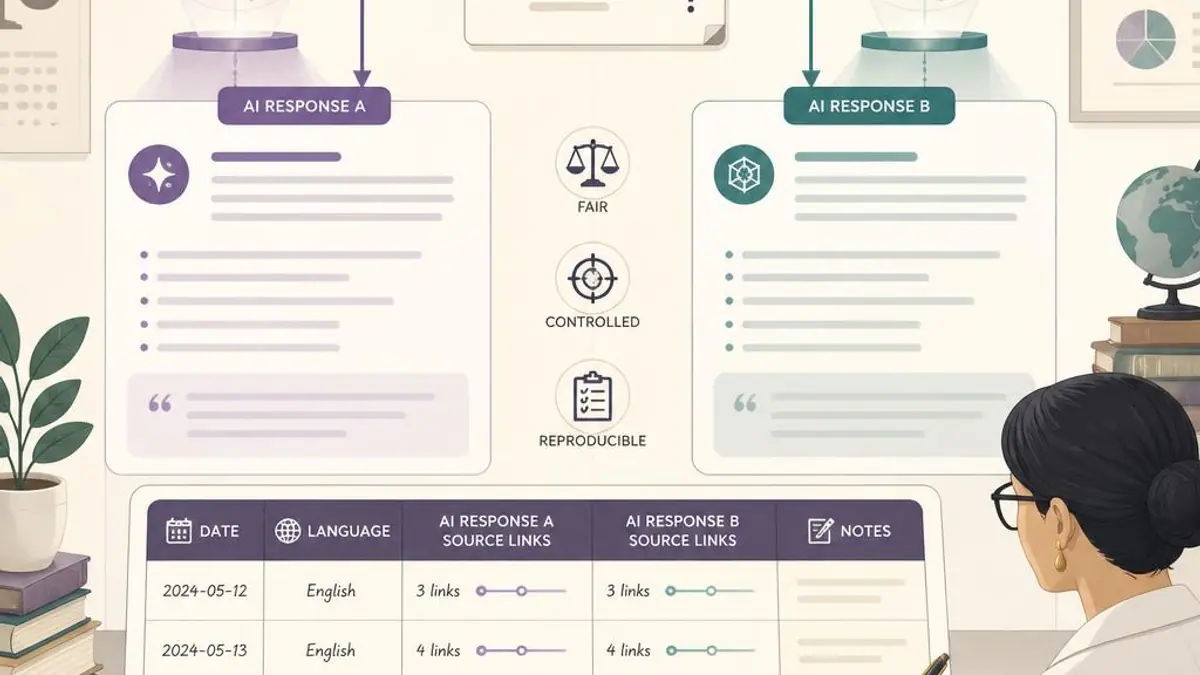
Compare AI engines using the same question cohort and clearly separated observations. Report citation presence, source links, timestamps and missing answers per engine instead of combining unlike outputs into a universal rank.
Document differences before calculating an average
An engine may return linked sources, snippets, citations in different positions or no source links for a response. Record what each available integration actually returns. A missing field is not necessarily a negative result.
Keep engine versions or displayed product names and check dates in the evidence log when available. Do not silently substitute an unrelated model result when one provider is unavailable.
Compare a common denominator
Use the same prompts, locale and review window. Calculate a per-engine citation count only over valid observations, and show how many runs were unavailable. If one engine ran yesterday and another ran after a major page change, explain the timing difference.
An illustrative result of two citations out of five completed checks is not directly comparable to two out of twenty. Show both numerator and denominator rather than a colored score alone.
Use the comparison to choose a review task
Open the sources from the engine where the relevant question was answered well. Look for answer gaps or unclear product facts that matter to the reader. Do not rewrite a page solely to optimize one provider's formatting quirks.
Repeat checks before interpreting a small difference as a trend. The aim is to improve an accurate public information base, not claim control over independent recommendation systems.
Define the comparison question first
A useful engine comparison answers a bounded question, such as whether two named services expose sources for a particular workflow or whether results differ for a specified buyer scenario. It is not a universal ranking of the assistants, nor proof of which one every prospective customer uses.
Define the product versions, date, region, language and mode of each check. Interfaces, retrieval paths and answer products change. If a setting is unavailable in one engine, record it as a limitation rather than pretending the environments were identical.
Keep prompts and sample cohorts equivalent
Use equivalent customer questions with the same task and level of detail. Record exact text and keep a separate prompt-version identifier. Do not demand that one engine cite a brand while asking another engine only for a general definition; that design builds the desired outcome into the comparison.
Separate informational, comparison and branded cohorts. Each tests a different user journey. When the same exact prompt is impossible across products, describe the difference and avoid presenting the resulting measures as directly interchangeable.
Capture outcomes the team can actually verify
For each response, capture whether the request succeeded, the response context, brand mentions, cited URLs and any explicit recommendation wording. Read the answer to understand the context. A linked source that explains a concept is not necessarily an endorsement, and an absent citation may reflect a different answer or missing observation.
Use a label set that means the same thing across both products. If a particular interface displays a source panel rather than inline links, document what you count and where the evidence appears. Keep raw status separate from your interpretation so the method can be reviewed later.
Interpret differences without declaring a universal winner
An engine may return different sources or wording for the same prompt. That establishes that these recorded outputs differed under the recorded conditions. It does not, by itself, establish a stable ranking or better performance for every user, location and question.
Inspect the cited passages and answers for possible reasons: subject scope, source availability, product context or a missing observation. Treat these as hypotheses until you have evidence. A one-day sample should not be used to promise that prioritizing one platform will solve a broader discovery problem.
Write a careful engine-comparison summary
Present the prompt set, date range, location, language, available-result count, classification rules and source ownership alongside the finding. Use example responses only when your usage and retention policies permit. Explain that a separate sample or later run could differ.
End with an action tied to a verifiable need. A shared factual gap may justify clarifying an authoritative page; engine-specific differences may justify further observation. Do not build a large collection of near-identical pages just because two engines phrased an answer differently.
Use a comparison table with coverage alongside results
Include one row per prompt and engine, with fields for date, language, location, response status, mention, source URL and recommendation classification. Show missing observations explicitly. If one service is unavailable for half the checks, a percentage based only on successful responses needs that coverage limitation beside it.
Report counts before percentages in a small study. Label the question cohort and the exact outcome represented by each number. A report of source links should not use a recommendation headline, and a report of successful responses should not be presented as a market-share study. Readers should be able to reconstruct the calculation from the displayed counts.
Keep exploratory checks outside the fixed comparison
Use a separate list for new scenarios, alternate phrasings and diagnostic prompts. These can help discover useful questions, but adding them to one engine's cohort midway through a study changes the comparison. If an exploratory prompt becomes important, version the protocol and begin a new comparable set.
Retain unfavorable and ambiguous answers under the same inclusion rules as favorable ones. Do not rerun a question until it gives the desired wording and then report only that response. If repeated sampling is part of the method, save all valid runs and explain how they are summarized.
Choose a business action from a bounded finding
Suppose both sampled engines describe a product limit inaccurately and the owned page is ambiguous. The business can clarify the limit and confirm the public explanation. Suppose instead only one response omits a brand while the page is accurate; the reasonable action may be additional observation rather than a rewrite.
Both examples are illustrative. The comparison should help choose work that can be verified on a page, not establish that one assistant is universally better or that a particular content edit will alter its behavior. State what evidence would justify the next action and when the team will review it.
Comparison sign-off checklist
Ask a reviewer to reconstruct one row before sharing the comparison. An attractive chart is not enough if the underlying observations are not equivalent.
- Confirm the same reader task and equivalent prompt wording across the compared engine products.
- Retain exact engine, date, market, language, mode and any unavailable configuration details.
- Display response coverage and keep failed requests separate from valid answers without a brand mention.
- Apply identical mention, citation and recommendation definitions and retain the supporting answer context.
- Show counts, denominators, cohort limits and the business action justified by the bounded finding.
Apply this workflow in RankZoro
Start with ai search engines and buyer questions and review the relevant RankZoro capability. Use the output to organize evidence and editorial work, not as a guarantee of search inclusion. Compare plans before running paid or credit-based actions.
Continue with How to Build a Buyer-Question Set for ChatGPT and Perplexity or Google AI Features and SEO: What Website Owners Should Check. These are supporting explanations, not independent proof of measured outcomes.
Sources and methodology
- Google: AI features and your website — Eligibility, search fundamentals, and reporting limitations.
- Google: creating helpful, reliable content — People-first content and evidence of experience.
- Google: spam policies — Doorway pages and scaled content abuse are not an expansion strategy.
Prepared by the RankZoro editorial team. Examples are illustrative unless explicitly identified as observed data. No customer outcomes or search-volume estimates are claimed.